You have decided a data engineer career is the path. That part is settled. What nobody has given you is the order.
So you open YouTube and find a video that starts with Spark. You open Reddit and someone insists you learn Kafka first. A friend says do a cloud certification. Another says certifications are useless, just build projects. Three weeks later you have watched forty hours of content, built nothing, and you are no closer to an interview than when you started.
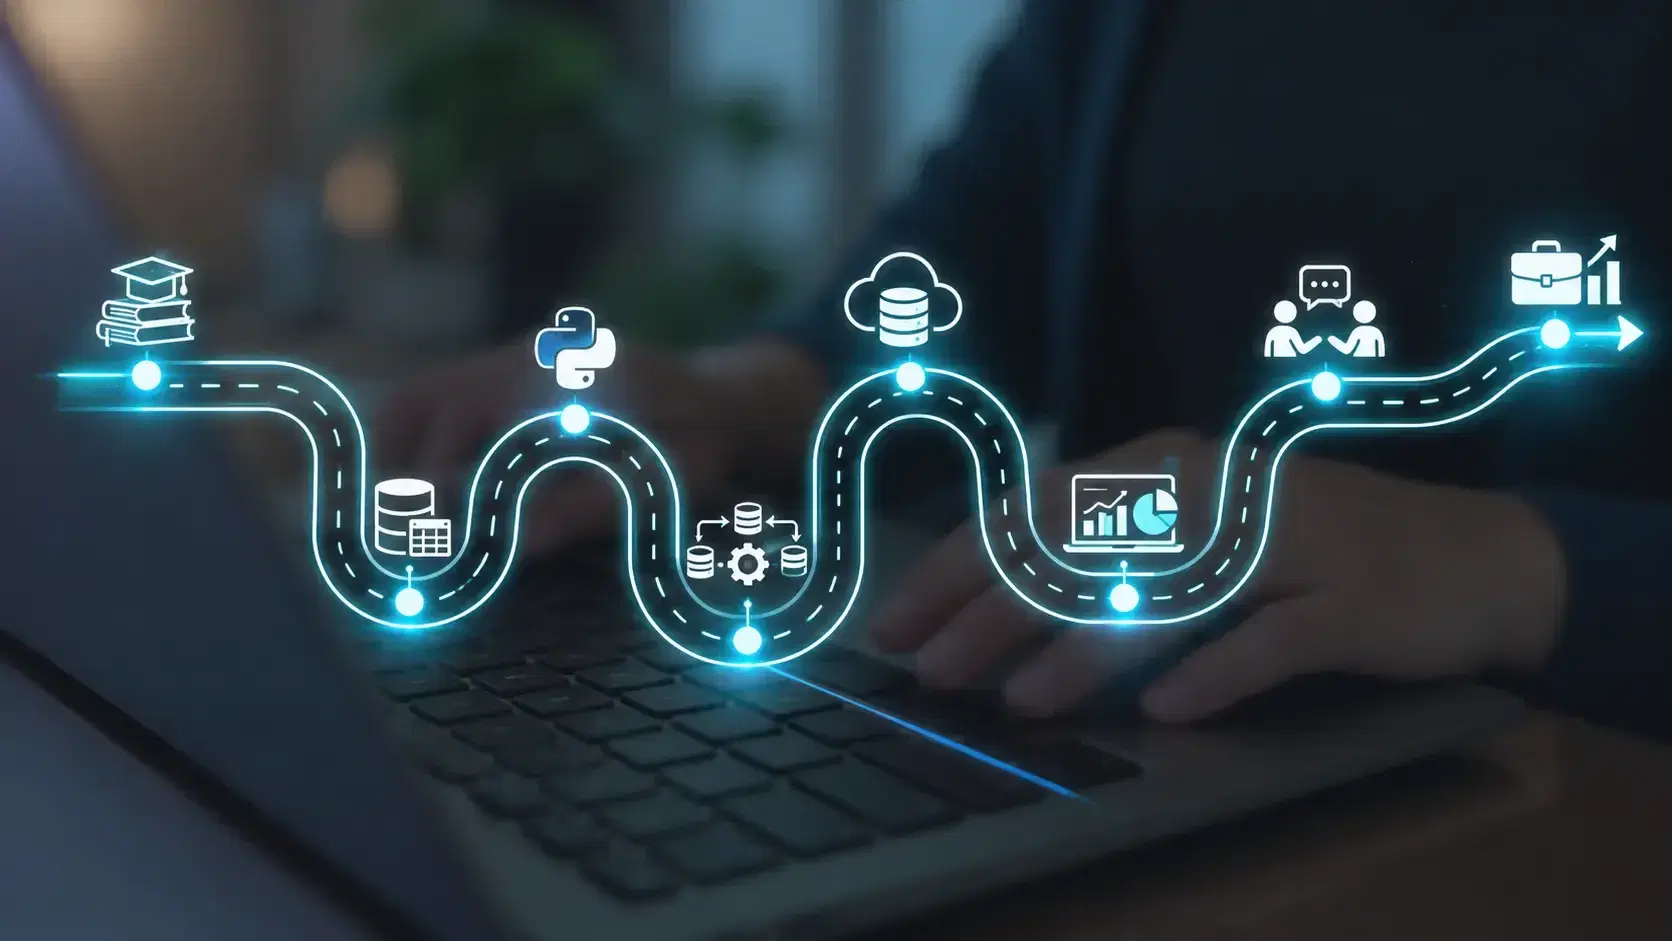
That is not a motivation problem. It is a sequencing problem, and it is the single most common reason people spend a year on something that should take six to ten months. This is the roadmap, in order, with the reason each step sits where it does.
One Honest Test Before the Roadmap Starts
Do this before you plan anything else, because it decides your starting point.
Open a blank file. Write a Python script that reads a messy CSV, cleans the column names, removes the duplicate rows and saves the result to a new file. No tutorial open, no video paused in another tab.
If you managed it, start at stage one below. If you could not, you have a programming gap rather than a data gap, and six to eight weeks of focused Python practice will save you three months of confusion later. Most graduates fall into the second group, and there is nothing unusual about it. Degree programs teach programming as a subject to pass, not as a working skill.
Stage 1 of Your Data Engineer Career Roadmap: SQL
Give this six to eight weeks and do not rush it.
SQL is the language of data and you will write it every single day of a data engineer career. Every interview starts here, and most candidates are eliminated here, which makes it the highest return investment on the entire roadmap.
Learn joins until every type is obvious. Learn grouping and aggregation. Then go further than most beginners do, into window functions, subqueries, common table expressions and query optimization. Window functions in particular separate people who pass technical rounds from people who do not.
The finish line is not completing a course. It is writing a genuinely complex query under time pressure without looking things up.
Stage 2: Python for Data Work
Four to six weeks, running alongside your SQL practice rather than after it.
You are not training to be a software developer, so ignore advice that sends you through a full computer science curriculum. You need a specific slice of Python and nothing more.
Focus on file handling, working with APIs, error handling and pandas. The skill that actually matters is writing a script that runs on its own, handles a failure without crashing, and tells you what went wrong when something breaks. That is closer to real pipeline work than any tutorial project.
Stage 3: How Data Is Actually Modeled
Two to three weeks, and this is the stage self taught learners skip.
Your degree covered databases from the application side, which is a different discipline. A warehouse is designed for reading and analysis, not for transactions, and that changes almost everything about how tables are structured.
Learn what fact and dimension tables are and why they exist. Learn star and snowflake schemas. Learn normalization properly, then learn when experienced engineers deliberately ignore it. Interviewers ask about this precisely because it separates people who understand the work from people who learned tools.
Stage 4: One Cloud Platform, Properly
Six to eight weeks on one platform, not three.
Pick AWS, Azure or Google Cloud. If you are unsure which, check job listings in your target city and count which appears most often. That is a better signal than any online argument about which platform is superior.
Go deep on three things. Storage, the warehouse service on that platform, and how identity and permissions work. Permissions are unglamorous and they are also what breaks most first jobs.
Spreading yourself across all three clouds gives you a resume line and no real capability. Depth in one transfers to the others far more easily than shallow familiarity with everything.
Stage 5: Pipelines and Orchestration
Four to six weeks, and this is where the job starts looking like the job.
Learn how pipelines are actually built, scheduled, monitored and recovered when they fail at two in the morning. Airflow is the most common orchestration tool you will see in listings. Databricks and Snowflake appear in a large share of data engineer job descriptions, so knowing what each is for and when you would choose it matters even before you use them daily.
Learn Git properly at this stage too. Not just commit and push, but branching and pull requests, because that is how every team works.
Stage 6: Three Projects That Could Break
Six to eight weeks, and this stage decides whether you get interviews.
A tutorial you followed is not a project. Build something that pulls real data from a public API, transforms it, runs on a schedule, handles failures gracefully and stores output somewhere queryable.
Make each one different. One batch pipeline, one that handles semi structured data like JSON, and one that includes data quality checks that catch bad records before they land. Put all three on GitHub with a readme that explains why you made each decision, not just what the code does.
In an interview, one project you can defend in depth beats ten you copied. Expect to be asked what broke and how you fixed it, so keep notes while you build. Nothing signals a real data engineer career start like a story about something failing at midnight.
How Long a Data Engineer Career Roadmap Really Takes
Roughly six to ten months at two to three hours a day. That drops to four to six months if you already program comfortably or study full time.
Add six to eight weeks at the front if you failed the Python test earlier. Anyone promising job readiness in ninety days is selling something, and the people who believe them usually restart the roadmap later anyway.
A Data Engineering Course After B.Tech and Other Degrees
Your degree changes where you enter this roadmap, not how far you can go.
A data engineering course after BTech usually lets you compress stages one to three, because programming logic and database exposure are already there. The gap is domain specific, which means warehousing concepts, cloud services and pipeline tools. The risk is different too. BTech students often skip fundamentals because the syllabus looks familiar, then struggle in interviews on exactly those topics.
After BCA or BSc, be honest about the Python test result before enrolling anywhere. Clear that first and you sit at the same starting line as anyone else.
After MCA, you generally have the strongest foundation and can move fastest through the early stages. Focus your energy on cloud, tooling and projects.
For career switchers from support, testing or non technical roles, this is very doable while working. Expect nine to twelve months, and know that testing backgrounds often make excellent data engineers because they already think about what breaks and why.
Choosing Data Engineering Training That Fits This Plan
Every institute claims to be the best data engineering institute in Mohali, Chandigarh or wherever you are searching. Ignore the claim and check whether the syllabus actually covers this roadmap. Good data engineering training maps to these six stages rather than to a tool list.
Ask for the syllabus and look for cloud with real hands on labs, not slides
Check that current tools appear, meaning Airflow, Databricks, Snowflake and a major cloud platform
Ask who teaches it and whether they have worked on production systems
Confirm you build and present at least three projects yourself
Ask whether live doubt support exists, because you will get stuck at stages three and four
Ask what the placement claim means in percentages and actual job titles
Then visit before you pay. Sit through a class, and talk to a current student without a counselor standing there. Fifteen minutes of that tells you more than any brochure. Walk away from guaranteed placement in writing, pressure to pay today for a discount, or any refusal to share the syllabus.
What Data Engineering Course Fees Depend On
Data engineering course fees vary widely, and the reason is easier to understand once you know what you are paying for.
Self paced online courses cost the least, often a few thousand rupees, but completion rates are low and lowest among people who just left a structured college routine.
Live online programs sit in the middle and add instructor access plus a schedule that keeps you moving. Classroom programs with projects and placement support cost the most, because they include trainer time, cloud infrastructure and hiring connections.
Two things genuinely drive the price. Trainer quality and cloud access. Cloud practice costs an institute real money, which is exactly why cheaper courses skip it.
Do not choose on price alone. A course without cloud work leaves you unable to answer stage four questions, and that costs far more in delayed hiring than you saved at enrollment. Most reputable institutes offer installments, so ask directly rather than assuming.
Mistakes That Break the Roadmap
- Starting at stage five because Spark and Kafka sound impressive
- Learning three cloud platforms shallowly instead of one properly
- Treating SQL as a week one topic to get past
- Collecting certificates instead of building projects
- Waiting until the roadmap is complete before applying anywhere
That last one matters more than it looks. Start applying around stage five, not stage six. Early interviews are free practice, they show you exactly which gaps are real, and occasionally someone hires you before you feel ready.
Your First Week on This Data Engineer Career Roadmap
Take the Python test today and be honest about the result. That single answer tells you whether you begin at stage one or spend six weeks on fundamentals first.
Then solve twenty SQL problems on any free practice platform and notice how the work feels. Read five entry level job listings in your city and write down every tool that appears more than twice, because that list is your real syllabus.
Finally, pick your route honestly. Self study works if you are genuinely disciplined about sequence. A structured program works better if you know you need accountability, live doubt support and someone checking your projects. Neither choice is wrong. Choosing the one that does not suit your temperament is what costs people a year.
Want to see what stage four actually looks like before you commit to anything? Sit in on a live data engineering class at IDEA Institute in Mohali or Ambala. No sales meeting, just a real session with students working through the same roadmap.